
Apple's Minions swarm idle Macs, cutting AI queue times from 10 hours to minutes
Apple's internal distributed GPU cloud pools idle Macs to run AI inference, turning a 10-hour wait into minutes for its teams.

Apple researchers unveiled Minions, a distributed system that aggregates idle Apple Silicon GPUs across macOS devices to run large-scale AI inference workloads. For decision-makers, it shows how underutilized hardware can be repurposed into a virtual GPU cloud, cutting queue times from over ten hours to minutes.
Apple's internal AI teams used to wait more than ten hours for GPU access. Now, with a system called Minions, inference jobs can often start within minutes. The change comes from a swarm of idle Macs across Apple's network, repurposed into a virtual GPU cloud. That's the headline number: queue times dropping from over ten hours to minutes, according to a research paper from Apple. The paper describes Minions as "a dynamic and distributed virtual GPU cloud that aggregates idle Apple Silicon GPUs across macOS devices to execute large-scale machine learning inference workloads." It's an internal tool, not a consumer product, designed to give Apple's employees better access to GPU resources for inference tasks. Instead of letting Macs sit idle, the system pools their compute power into a shared, fault-tolerant resource.
The infrastructure leverages recent Mac hardware. Apple's Mac mini and Mac Studio support clustering using RDMA (Remote Direct Memory Access) over Thunderbolt 5, which allows compute and memory to be combined across devices. That means a model too large for a single machine can be loaded across multiple Macs. Minions creates a fault-tolerant pool of inference workers, so if one device fails, tasks are reassigned. The system has four components: Minion Server, PostgreSQL Metadata Store, Minion Executor, and Minion Watchdog. The Minion Server coordinates requests and breaks them into subtasks. The Minion Executor runs inference on a Mac's GPU, uploads results to S3, and reports status back through the server. The Watchdog monitors for failures, like a Mac not responding, and re-assigns tasks. Database stats feed into Grafana dashboards for real-time visibility.
Apple's approach is not the same as an Nvidia cluster. Nvidia focuses on throughput, latency, and efficient GPU utilization for large models. Minions focuses on hardware availability and utilization, redistributing idle resources on the network. It's not necessarily intended to run the largest models, but to make better use of what's already there. For a company that sells premium Macs, this also demonstrates the potential of Apple Silicon for AI workloads, even if it's not a commercial offering. The research paper is a quiet but strategic signal: Apple is building its own AI infrastructure, using its own chips to reduce reliance on external cloud providers and Nvidia GPUs.
For executives, this is a lesson in resource optimization. Many companies have underutilized GPUs, whether in data centers or on employee devices. Minions shows a way to turn that idle capacity into a shared resource, cutting queue times dramatically. It also highlights the growing importance of distributed inference, especially as models grow and centralized clusters become bottlenecks. The 10-hour queue is a reminder that compute is a scarce resource, but sometimes the answer is already in your building. As AI workloads expand, expect more organizations to explore similar distributed approaches. The research paper offers a blueprint for pooling idle hardware, and the implications extend beyond Apple: any company with a fleet of devices could potentially adopt a similar model to stretch its AI budget further.
Strategically, Apple's move fits a broader industry trend toward edge computing and distributed inference. By using its own silicon, Apple keeps AI workloads in-house, which has implications for data privacy, latency, and cost. It also strengthens the ecosystem story: Macs are not just consumer devices, but building blocks for AI compute. For peers in similar roles, the takeaway is to audit existing hardware before buying more. The Minions system is a reminder that innovation often comes from rethinking what you already own, not just acquiring new resources.
This story's Key Insights and Take-aways are locked.
Create a free account to unlock Executive Actions for one credit.
Register to UnlockAlways free for Executives Club members. Join the Club
More in Technology
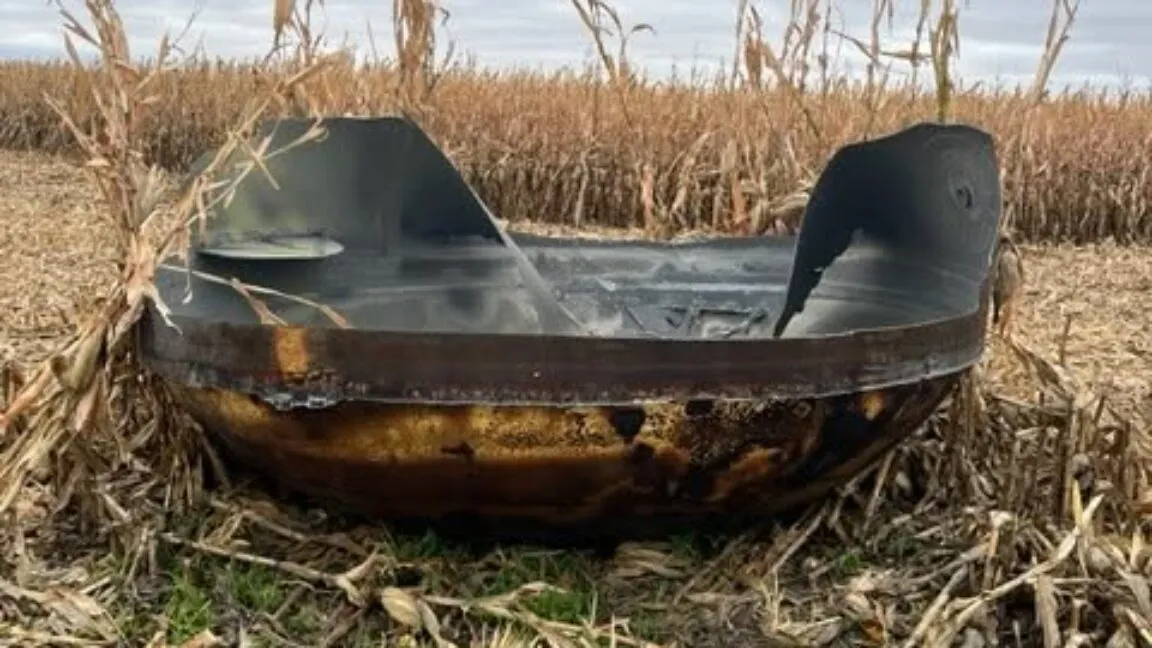
A Chinese rocket deorbited over Minnesota and landed in a farmer's cornfield
Experts tied the fragment to LandSpace's Zhuque-2E, which launched on September 15 and shed debris over the American Midwest after deploying 10 satellites.
JPMorgan Chase deploys first $5B into defense tech and hypersonic missiles
The bank is moving off its balance sheet to back robot factories, hypersonic missiles, and supply chains, signaling a new era of bank-backed military innovation.

Cop fired after sharing Flock login with ICE husband: 983 searches
A Savannah officer's shared credential let an ICE agent run hundreds of plate searches on Hispanic drivers, exposing a surveillance backdoor.