
OpenAI's Codex traced 600 ChatGPT slowdowns. It shipped just 15 exact fixes.
OpenAI's Performance Factory ran 1,700 automated investigations in three months; the gap between diagnosis and shipped code is the real story for enterprise AI buyers.
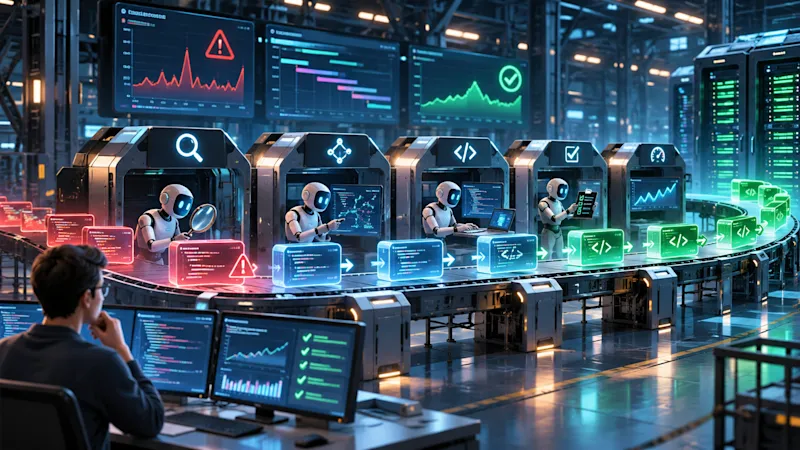
OpenAI's performance engineering team built the Performance Factory, a Codex-powered internal system that ran more than 1,700 investigations and identified root causes in over 600 ChatGPT performance regressions in just over three months. The number that matters for buyers is the funnel: only around 15 shipped fixes were the exact pull requests Codex authored, which makes review and verification, not agent output, the binding constraint on agentic engineering.
OpenAI's internal Performance Factory, a Codex-powered system that hunts down why ChatGPT gets slower, ran more than 1,700 investigations in just over three months, according to an exclusive engineering report shared with VentureBeat. It pinned the root cause in more than 600 of them, an average of 17 automated investigations a day. Now the number that should stop you: of those 600-plus diagnosed regressions, roughly 400 advanced to a proposed fix, about 50 of the fixes that eventually shipped were influenced by or matched what the agent suggested, and only around 15 shipped fixes were the exact pull requests Codex authored. Diagnosis at machine speed. Remediation still at human speed.
That gap is the story. OpenAI's performance team says the results fall short of its ambitions for automated remediation. But the team also points out that much of the labor of resolving a regression is not the clever part. It is detecting the problem, identifying its cause, tracking it across days, and verifying recovery. Those are the steps Performance Factory has automated, and they are the steps that quietly eat engineering capacity at almost every company running software at scale.
The system did not start as a grand architecture. OpenAI's performance engineering team began with manual investigations: when a service slowed, engineers read logs and traces, reviewed code changes, and debugged live systems, building more than 30 specialized tools to speed that up. Codex changed the shape of the work. Instead of searching codebases and telemetry by hand, engineers could ask the agent why a service had become slower. But they still had to steer it, so the team wrote a reusable Codex skill called perf-forensics that captures the performance team's own investigation procedures for the agent to reproduce. After testing and refining, OpenAI could hand Codex a performance alert and get a diagnosis back in a single run. For a while, engineers were the plumbing, copying alerts into Codex and pasting findings into Slack. Then the team simply connected the alerts to cloud-based Codex sessions.
Diagnoses still ended with a human, and the ChatGPT performance team was fighting regressions almost daily. So it built a regression tracking system, then realized each tracked regression could become a task Codex would investigate and push through stages: root cause, proposed fix, verification. That became the Performance Factory's task-based architecture, where each task holds its own state and findings so different agents can work the same problem at different stages. A task record carries a free-form field for agent notes plus structured metadata such as when a regression began and when its root cause was identified. Crucially, agents do not dump profiling data into the record. They log the relevant metrics, queries, and high-level findings, and the next agent can rerun those queries to verify. Four components hold it together: a task service that stores tasks and progress, with workflows defined in configuration files and markdown prompts; a dispatch loop that starts a Codex session when a task is ready to advance; an internal API for running Codex in the cloud with access to OpenAI's code repositories and observability infrastructure, with permissions controlled and agent actions tracked; and subscriptions that connect tasks to external events, so a task can pause until an engineer responds on GitHub.
The first concrete implementation is the Regression Workflow. A configured alert fires, a task is created, and agents investigate using perf-forensics. The agent works out what changed, when performance started deteriorating, and which requests were affected, then examines code changes, logs, and traces to establish the cause. That is where OpenAI hit a familiar AI failure mode: agents sometimes stopped at the first plausible explanation even when the evidence did not fully support it. The fix was adversarial review, a separate Codex session that receives the entire task record but starts with a fresh context and explicit instructions to find gaps in the diagnosis, verify the supporting evidence, and test alternative explanations. In one investigation, an agent blamed failing ChatGPT conversations on image download errors. The reviewer noticed the internal service responsible for locating files had already recovered while image requests kept failing, and reopened the case because the original diagnosis did not explain the continuing failures. Adversarial review initially sent back a substantial number of diagnoses for further investigation; after the team improved the original investigator's instructions, it now returns around 25%.
Only after a diagnosis clears that review does Codex propose a fix and open a pull request. An engineer then decides whether to merge it. That is the design choice worth copying: the agent gets permission to act inside a defined envelope, with code access, observability access, and tracked actions, and a person keeps the merge button. It is also why the 15 exact Codex-authored pull requests matter less than they look. The scarce resource is not agent output. It is trusted, verified change.
For enterprise leaders watching the coding-agent race, Performance Factory is a preview of where the bottleneck moves next. AI agents from multiple vendors now write and change code fast enough that human review of every change becomes the constraint. OpenAI's answer is to make the workflow, not the prompt, the unit of automation: defined stages, state carried between agents, evidence that can be re-verified, and a second agent whose only job is to disagree. Performance engineering is a useful test case because it comes with objective signals. Alerts fire, metrics move, and recovery is measurable, so you can tell whether the agent was right. Most back-office workflows do not ship with that scoreboard, which is exactly why teams should build one before they hand over the work.
The honest read is that OpenAI automated the repetitive work, left the judgment calls to engineers, and said so publicly. Of more than 600 root causes identified, only around 15 shipped as untouched Codex pull requests. Any board evaluating agentic tooling should ask the same question of every vendor demo: not how many tasks the agent completed, but how many changes were merged, verified, and still holding. The companies that win the next phase of AI-assisted engineering will not be the ones with the most agents. They will be the ones whose review layer, observability, and permission controls are strong enough that agents can be trusted to run unattended.
This story's Key Insights and Take-aways are locked.
Create a free account to unlock Executive Actions for one credit.
Register to UnlockAlways free for Executives Club members. Join the Club
More in Technology

Anthropic mathematician claims Claude helped crack the Riemann hypothesis
If the proof holds, AI has toppled math's most famous open problem; if it does not, it is a case study in announcing breakthroughs before anyone verifies them.

AI's $4 Trillion Wipeout Erases Nasdaq's Gains for the Year
A brutal week took roughly $4 trillion off the AI sector and left the Nasdaq flat for the year, and the damage ran the full length of the supply chain.

Anthropic mathematician says AI proved the Riemann hypothesis. Verification will take time.
A single unverified claim from inside Anthropic now sits against more than 160 years of open mathematics, and the gap between asserting a proof and surviving peer review is the entire story.