
Microsoft, Apple, Airlines, NSA: Four Failures in Days, One Shared Blind Spot
The common thread in a run of high-profile technology failures is not one bad update but the concentration baked into the modern stack, and the executives who own that dependency map are the ones on the hook.
Microsoft, Apple, airlines and the U.S. National Security Agency all suffered major technology failures in recent days, a cluster Scientific American flagged by asking, bluntly, what the hell is going on. The consequence for decision-makers is that vendor concentration has become a board-level resilience risk rather than an IT footnote, and most companies cannot name which revenue processes die when a single provider goes dark.
The list reads like a bad week at the wrong scale. Microsoft. Apple. Airlines. The U.S. National Security Agency. All of them suffered major technology failures in recent days, and Scientific American did not dress it up: what the hell is going on?
That is the right question, and the honest answer is less comforting than a villain. There is no single bug to point at in the reporting. What the source describes is a cluster: a run of high-profile failures landing close enough together that the pattern stops looking like bad luck. When outages bunch up across organizations that share almost nothing on the surface, a bank and a planemaker and an intelligence agency, the useful instinct is to stop asking which component broke and start asking why so many critical systems are wired closely enough together to break in sympathy. Clusters happen because the modern stack has shared upstreams: a handful of cloud regions, a handful of identity providers, a handful of network paths, a handful of security agents sitting in the kernel of everything. Shared upstreams mean shared failure modes, and they mean shared timing, because updates also ship on a shared cadence.
The structural story starts with consolidation. Over the past decade and a half, enterprises moved workloads onto a small number of hyperscale cloud providers, standardized on a couple of operating systems, and outsourced identity, payments, security and payroll to a short list of vendors. The economics were irresistible: cheaper, faster, and staffed by specialists you could never hire yourself. The trade-off rarely makes it onto the same slide. A bad day for one provider becomes a bad day for thousands of customers simultaneously, and those customers typically discover mid-incident that their disaster recovery plan quietly assumed the provider was the disaster recovery plan.
Aviation is the cleanest illustration of how that cascades. An airline is not one system; it is a stack of them, reservations, crew scheduling, dispatch, gate operations, each built at a different time on different assumptions and stitched together by integrations that work until they do not. Historically, that is why a failure in a single layer can ripple into delays that outlive the original glitch by hours. Aircraft stay parked not because anything mechanical failed but because the software that tells crews and gates where to be stopped talking.
Then there is the NSA entry, which deserves its own paragraph because it punctures the standard corporate reflex. The default response to any outage story is to spend more: another monitoring layer, another vendor to watch the vendors, another dashboard. The National Security Agency is the organization that already did all of that, at a scale no private company can match, staffed by people whose entire job is thinking about how systems fail. It still went down. That does not make security spending wasted. It does mean complexity is the failure mode that spending tends to add to rather than subtract from, and that no budget buys immunity from a dependency you did not map.
For executives and boards, the practical question is not whether the stack is resilient in theory. It is which revenue-generating processes stop dead if one vendor disappears at 9 a.m. on a Tuesday. Most companies cannot answer that inside a week. The dependency map is usually scattered across procurement, IT, finance and whatever business unit signed its own software contract three years ago without telling anyone. That is a governance gap, and it belongs on the audit committee agenda next to cyber, not buried in an operational risk register nobody opens.
The external pressure is tightening at the same time. Supervisors in several major markets have been steadily reclassifying operational resilience from a private misfortune into a supervisory obligation, with expectations around impact tolerances and tested recovery plans. Insurers, for their part, typically price business interruption with a hard look at exactly this kind of concentration, and a visible cluster of public failures tends to show up at renewal. A run of outages like this one is the sort of evidence that gets quoted back at you.
None of this is an argument for retreating to private data centers or rebuilding everything in-house. It is an argument for knowing what you own. The companies that come out of this stretch looking competent will not be the ones with the fewest vendors. They will be the ones whose customers never noticed anything happened, because somebody had already asked the boring question: what breaks first, and who is allowed to fix it at 3 a.m.?
This story's Key Insights and Take-aways are locked.
Create a free account to unlock Executive Actions for one credit.
Register to UnlockAlways free for Executives Club members. Join the Club
More in Science

Anthropic's I.P.O. Made Rank-and-File Researchers Worth Tens of Millions
Researchers who joined just a few years ago are now worth tens of millions, and the windfall resets the pay benchmark for every private A.I. lab still paying in paper.

Sea Lion Culling Strategy Fails: New Model Says Killing Them Won't Save Salmon
The latest research from AAAS overturn a long-held conservation assumption, forcing policymakers to rethink critical resource allocation in marine ecosystems.
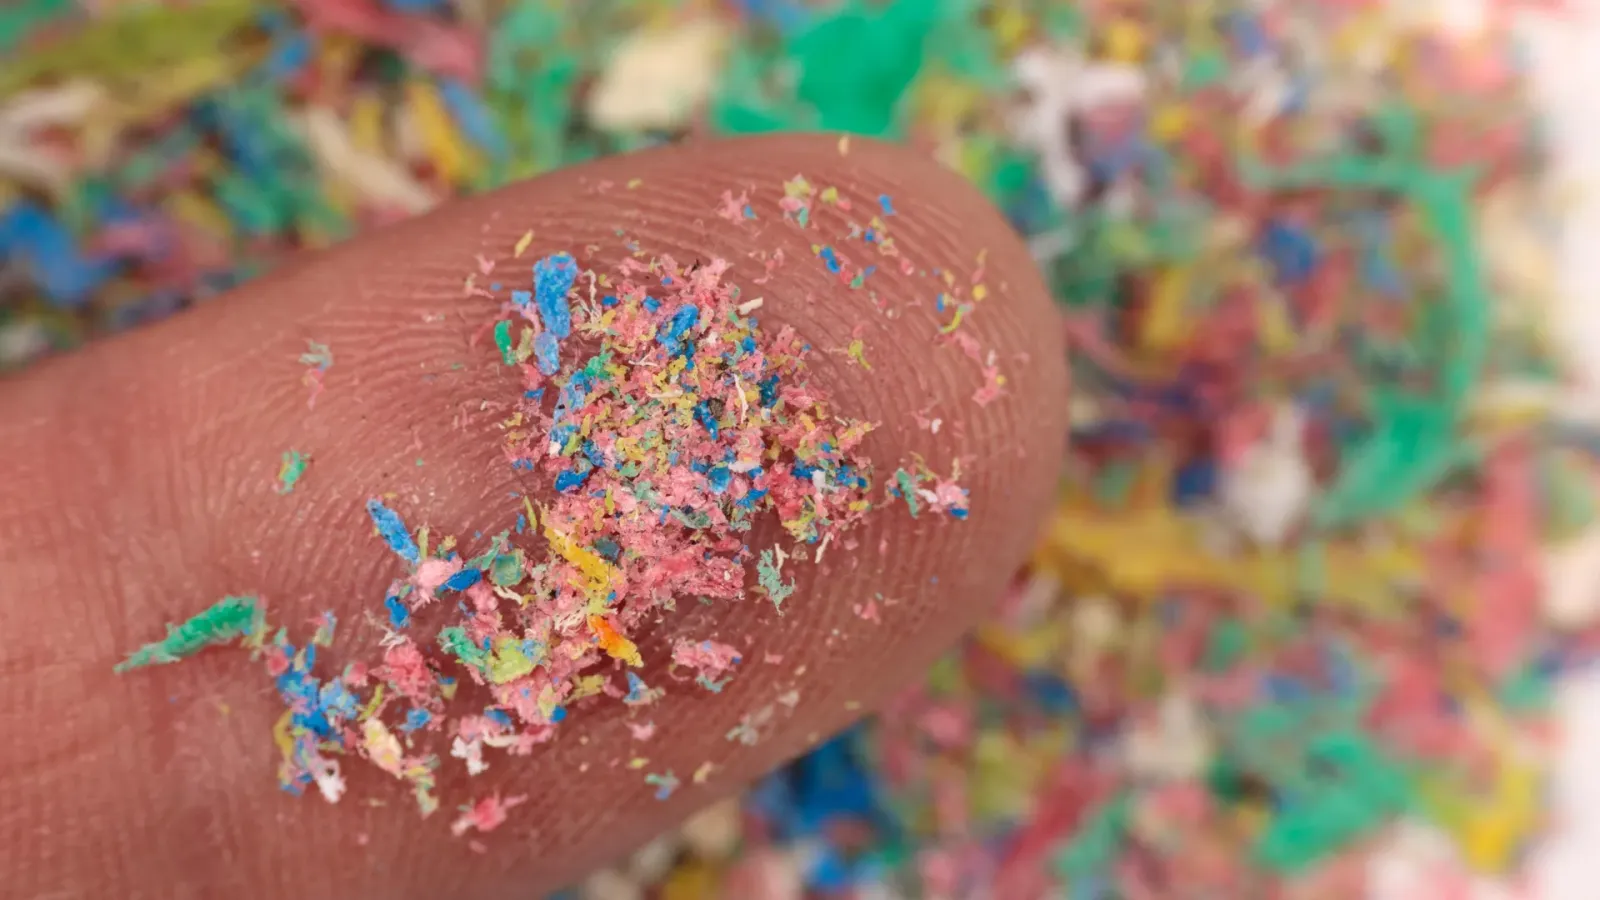
Microplastics do more than pile up: they react with water to damage cells
Scientists have found that plastic particles can generate highly reactive molecules in water, a mechanism that could explain links to heart attacks, strokes, and neurological disorders.